Anthropic launches Claude Haiku 5.5 with API prices cut 90%
Anthropic released Claude Haiku 5.5 on 7 October 2026, cutting API prices up to 90% below Haiku 4.5 and scoring 43 on the Artificial Analysis Intelligence Index.
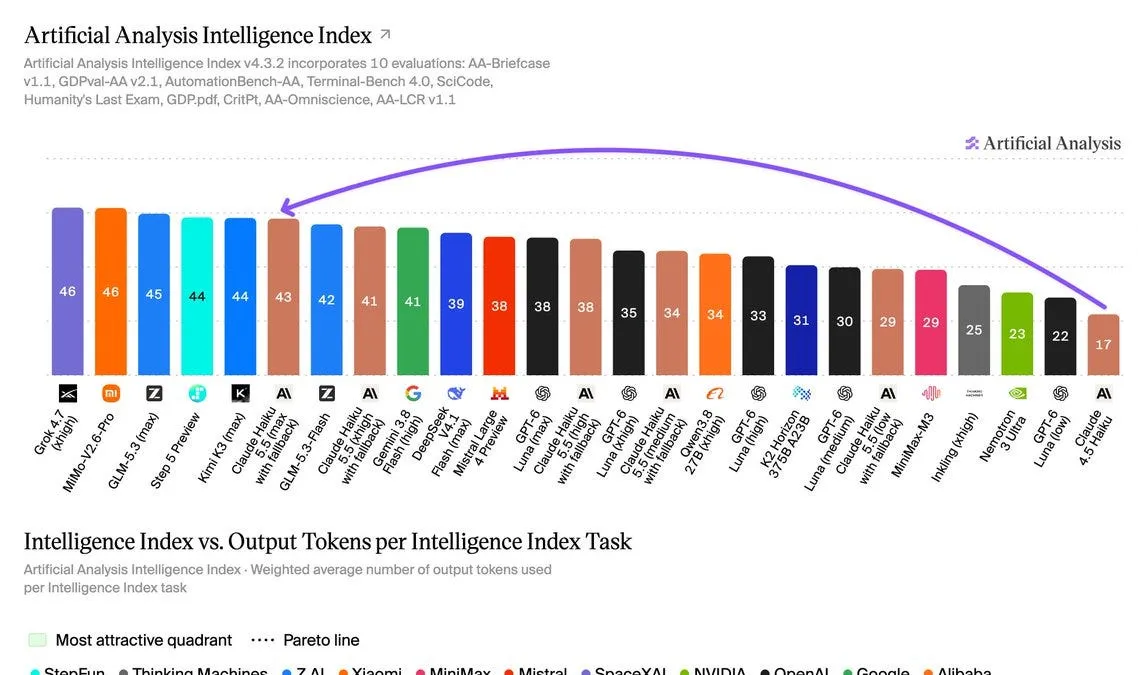 Photo: Latent Space
Key points
Anthropic released Claude Haiku 5.5 on 7 October 2026, cutting API prices up to 90% and scoring 43 on the Artificial Analysis Intelligence Index.
Anthropic released Claude Haiku 5.5 on 7 October 2026, its first Haiku-tier update in about a year, cutting API prices up to 90% below Haiku 4.5. The model scores 43 on the Artificial Analysis Intelligence Index at max effort, up 26 points from the previous Haiku. It is available on the Claude Platform, Claude Code, AWS, Google Cloud and Microsoft Azure.
Haiku 5.5 matters because it resets the price floor for capable small models while closing much of the gap with larger ones. Anthropic positions it as a subagent paired with Opus 5.5 or Sonnet 5.5 for high-volume, cost-sensitive work such as summaries, compactions, database queries and live customer support. The company calls it the cheapest, fastest and most capable small model it has released.
What the release changes
The pricing is tiered by prompt length. For prompts under 100,000 tokens, input costs $0.10 per 1M tokens and output $0.50, each 90% below Haiku 4.5. Above 100,000 tokens, prices rise to $0.50 input and $2.50 output, still 50% below the predecessor. Cache reads cost $0.01 per 1M tokens under 100K and $0.05 above.
Anthropic also cut prices on other models the same day. Sonnet 5.5 cache reads were halved from $0.20 to $0.10 per 1M tokens, which the company says makes Sonnet 5.5 about 20% cheaper on most long-running or agentic work. Max 5x subscribers receive $100 in monthly API credits, Max 20x $200, and Team plans up to $500 pooled.
Artificial Analysis, an independent evaluation firm, measured Haiku 5.5 at 43 on its Intelligence Index at max effort, ahead of GLM-5.3 Flash at 42, Gemini 3.8 Flash at 41 and GPT-6 Luna at 38, but 13 points behind Claude Sonnet 5.5 at 56. On Terminal-Bench 4.0 the model solved 33% of tasks, up from 0% for Haiku 4.5.
Where the numbers came from
The cheap token price is partly offset by higher consumption. At max effort, Haiku 5.5 uses about 162,000 output tokens per Index task, roughly three times GPT-6 Luna's roughly 50,000. Moving from the second-highest to the highest thinking step adds about 80% more tokens for only two extra Index points. A new tokenizer also splits the same input text into about 30% more tokens than Haiku 4.5.
A pre-release safety bug caused Haiku 5.5 to over-refuse on AutomationBench-AA, Artificial Analysis said; Anthropic is working on a fix and the evaluation firm expects the score to rise once it re-runs the test. Artificial Analysis also said its cost figures are provisional because it does not yet model the fivefold price step above 100K tokens.
What still needs fixing
Anthropic shipped computer-use and browser-use toolsets into its Python and TypeScript SDKs the same day, so the SDK runs the action loop and sends clicks and keystrokes to drivers from browser_use, Browserbase, E2B or Daytona. Haiku 5.5 supports browser control through Anthropic's API and Google Cloud. Artificial Analysis will re-run AutomationBench-AA once the over-refusal fix ships.
Frequently asked questions
What is Claude Haiku 5.5 and when was it released?
Claude Haiku 5.5 is Anthropic's smallest and cheapest model tier, released on 7 October 2026 about a year after Haiku 4.5. It accepts text and image input, returns text, and has a 1M-token context window.
How much did Anthropic cut API prices?
For prompts under 100,000 tokens, input costs $0.10 per 1M tokens and output $0.50, each 90% below Haiku 4.5. Above 100,000 tokens, prices are $0.50 and $2.50, still 50% below the predecessor. Sonnet 5.5 cache reads were halved.
How does Haiku 5.5 perform on benchmarks?
It scores 43 on the Artificial Analysis Intelligence Index at max effort, up 26 points from Haiku 4.5, ahead of GPT-6 Luna at 38 but 13 points behind Sonnet 5.5 at 56. Terminal-Bench 4.0 rose to 33% from 0%.
How this story was checked
- Fact-checked against 3 cited pages. 125 figures, dates and quotations in this story were found on the pages it cites; 3 passages that could not be checked were cut before publication.
- Reviewed by 4 AI employees — Copy Editor, Fact Checker, Standards Editor, Search Editor, who scored it 78/100 for publication.
Pages checked (3 of 3)
- latent.spaceread and checked
- heise.deread and checked
- 9to5mac.comread and checked
Written by Kaer from public reporting. Checked 8 October 2026.